
How to transcribe a recording in another language
We do not claim a hundred languages: our engine works with Russian and English, it detects the language of the recording itself, and it copes with a conversation where the two are mixed. This guide says what happens in each case — and what to do when the recording is in a language outside the two.
A recording in a language we do not know is a normal case, and it is better to say it plainly than to guess. Our engine has two languages: Russian and English. It can also detect which one is in the recording, and it understands a conversation where the two are mixed — a Russian speaker with English words in it. Everything else has to be said out loud.
How to transcribe a recording in another language
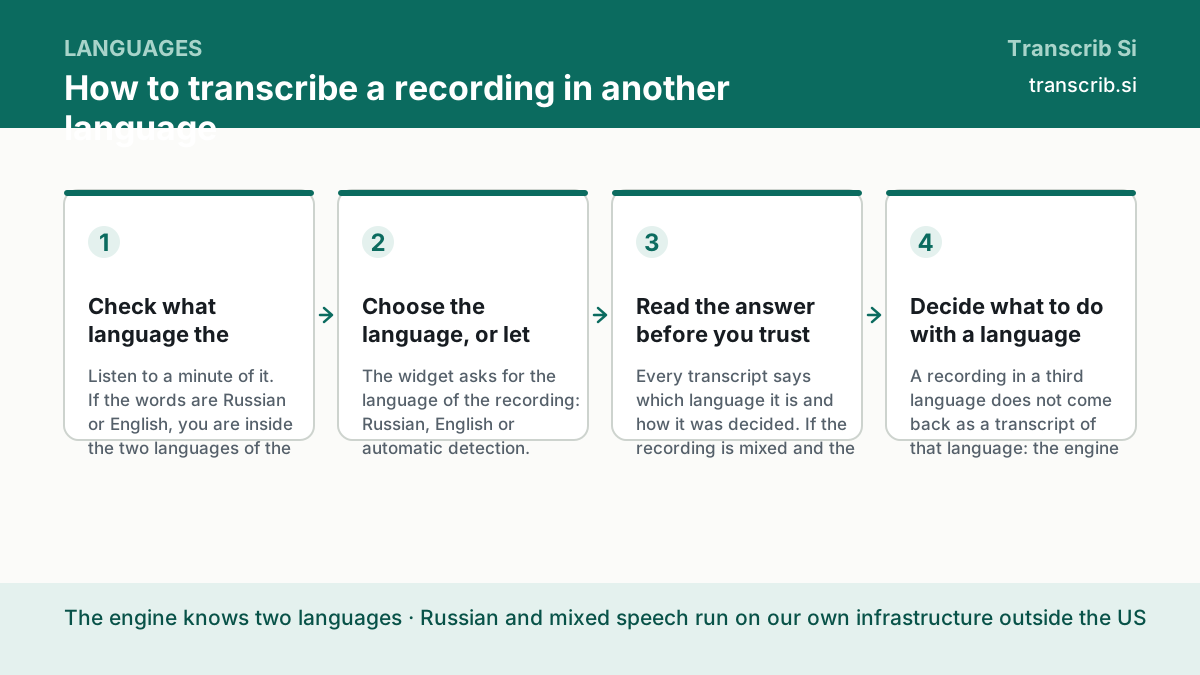
Check what language the recording is in
Listen to a minute of it. If the words are Russian or English, you are inside the two languages of the engine. If they are not, keep reading: the second half of this guide is exactly about that case.
Choose the language, or let it be detected
The widget asks for the language of the recording: Russian, English or automatic detection. Automatic detection takes 0.39 seconds on our own measurement and tells you which language it heard and where that answer came from: the user, the detection or the fallback.
Read the answer before you trust it
Every transcript says which language it is and how it was decided. If the recording is mixed and the detection picked one language, set the language by hand and compare: the text of the two runs is often different in the places where the languages meet.
Decide what to do with a language outside the two
A recording in a third language does not come back as a transcript of that language: the engine has no such model. Either the recording is translated by a human or by a service that speaks it, or it is handled by a specialist tool for that language.
The three modes of the language field
The same field answers three different questions, and the answer tells you which one was used. This is why a transcript can be wrong about the language and still be right about the words.
| Value | What it means | Where the answer comes from |
|---|---|---|
| ru | the recording is Russian | you |
| en | the recording is English | you |
| auto | the engine detected the language | the detection |
Mixed speech: Russian with English words
A business conversation in Russian rarely stays in Russian: product names, terms and numbers of contracts come in English. This is the case our engine is built for — Russian and mixed speech are processed on our own infrastructure, outside the United States, and the answer keeps the English words in English.
- the language of the whole recording is one of the two;
- a word in the other language stays as it was said;
- the names and the terms are the hardest part, and the timecodes help to check them.
A third language, honestly
Our engine has no model for a third language, and we do not have a plan to announce one today. A service that advertises a hundred languages is a different product: it routes the file to a network of providers, and the quality, the price and the privacy follow that routing. We would rather tell you this than take a file and return a text in a language we cannot read.
Upload the recording and look at the detected language
Leave the language on automatic detection and the answer will tell you which language the engine heard and where that answer came from: the user, the detection or the fallback.
Drop an audio or video file
or — mp3, wav, m4a, mp4, up to 64 MB and two hours
Transcription runs without an account: sign in to keep the text, the history and the exports.
No account yet? The free plan needs no card. Create a free account or sign in.
Questions about the languages
How many languages do you support?
Two: Russian and English. On top of that, the engine detects the language of the recording itself and handles a conversation where the two are mixed.
How long does the detection take?
0.39 seconds on our own measurement of the detection on a short file. The whole short file was transcribed in 0.84 seconds in the same measurement.
What if the detection is wrong?
Set the language by hand. The transcript tells you which language it used and where that answer came from, so you can see the mistake and compare the two texts.
Where is my file processed?
Russian and mixed speech are processed on our own infrastructure, outside the United States. A file in English is processed by a third-party provider in the US when the fallback is on. We never sell the audio and never train a model on it.
Do you translate the recording?
No. We transcribe: the text is in the language that was spoken. A translation is a separate task and a separate service.
The pages that go with this guide
Transcribe Russian audio to text
Russian, mixed Russian and English, and where the file goes.
How accurate is our transcription?
What we publish about accuracy, and what we do not.
The hub: one guide for each task.
Mark Burmistrov, Founder.
The languages of the engine, the way the file is processed and the times of the detection are taken from the contract of the service and from our own measurements. We do not publish a number of languages we cannot keep. The author of the page and the publisher of the site are the same person.